Independent verdict: LibreCrawl is an MIT-licensed desktop SEO crawler positioned as a free, customizable alternative for crawling sites, extracting SEO data and exporting results. Its strongest fit is independent consultants and technical teams that value local control and are willing to test a younger crawler. The main adoption mistake would be to treat an open repository or a high star count as proof that its recommendations, data or scores are correct for every site.
Its strongest differentiator is inspectability. Adoption should still be decided by crawl parity and false-positive rate on the team's own site.
What LibreCrawl actually does
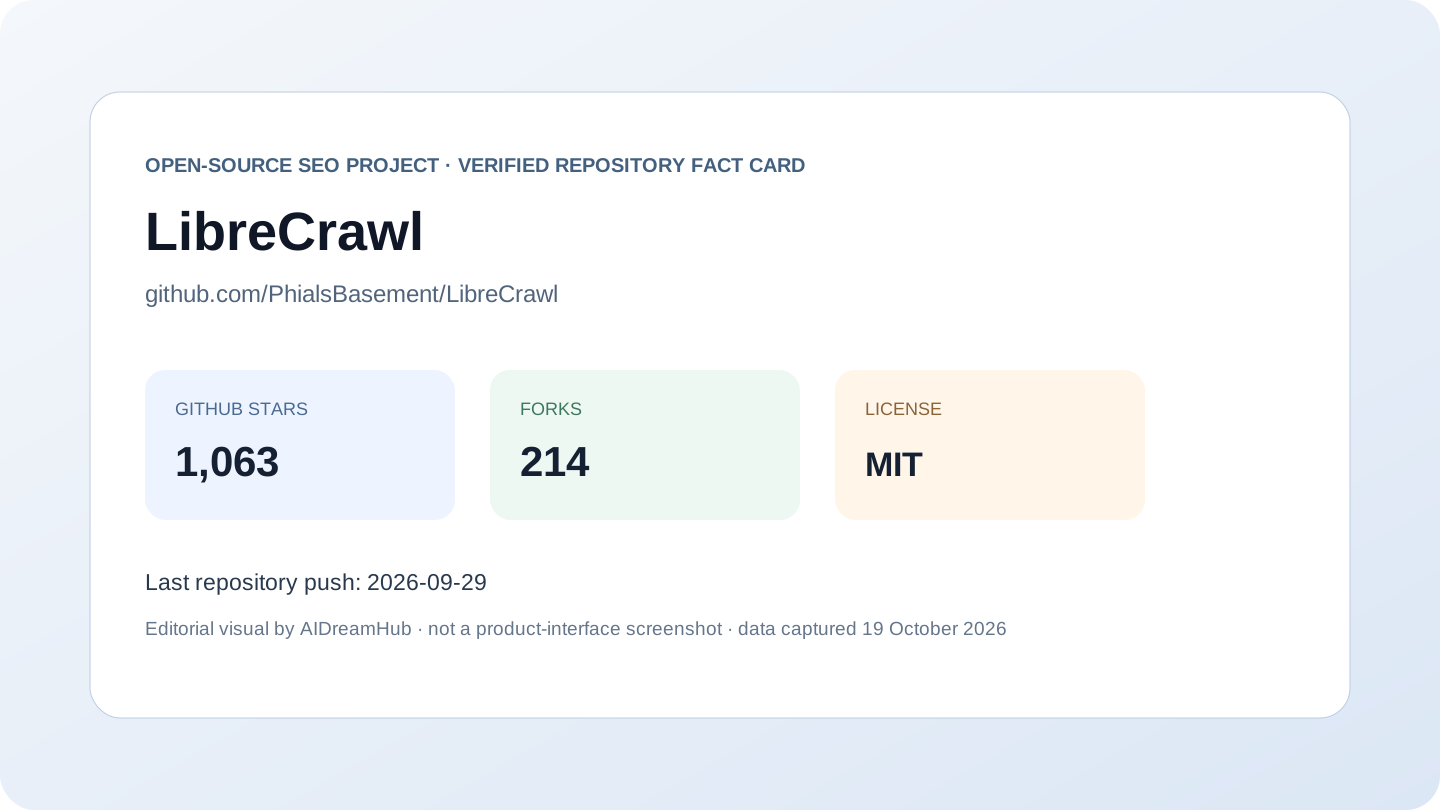
LibreCrawl should be evaluated as a crawler tool, not as a universal SEO platform. The verified repository description is: “Free desktop SEO crawler - open source alternative to Screaming Frog and similar tools. Crawl websites, analyze links, extract SEO data, and export results without subscription fees. Fully customizable and extensible!” The distinction matters because a crawler, a structured-data library and an MCP connector solve different layers of the SEO workflow.
| Verified capability | Practical meaning |
|---|---|
| Focuses on local desktop crawling without a recurring software subscription. | Check the official setup and version before relying on it. |
| The open code can be extended for custom extraction and team-specific checks. | Treat integrations as separate trust and cost boundaries. |
| The project began in 2025, so its scale behavior, rendering coverage and reporting polish should be benchmarked rather than inferred from the feature list. | Benchmark the behavior on a representative site or account. |
Current GitHub evidence snapshot
The table below was captured on 19 October 2026. “Latest” means recent repository activity in this review, while “hot” is a blend of attention and activity. Neither term is a quality guarantee.
| Evidence | Observed | How to interpret it |
|---|---|---|
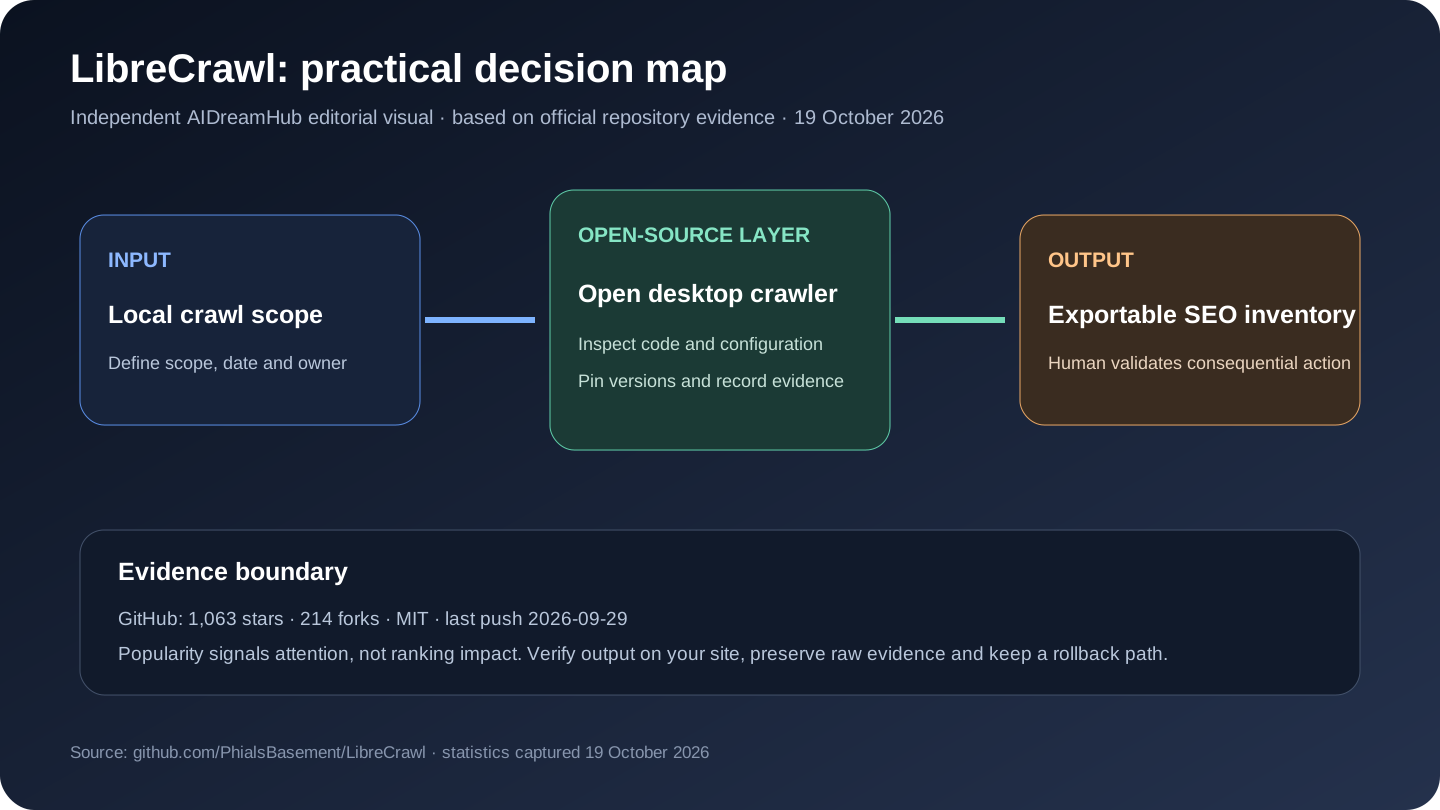
| Repository activity | 1,063 stars · 214 forks | Community attention and reuse signal; not proof of SEO outcomes |
| Last push | 2026-09-29 | Recent code activity; inspect releases and breaking changes before production |
| License | MIT | Confirm obligations for distribution, SaaS use and modifications |
| Primary stack | Python | Indicates the likely maintenance skills, not feature completeness |
Best-fit workflows
Best fit: independent consultants and technical teams that value local control and are willing to test a younger crawler.
- Create a local inventory of titles, headings, canonicals and status codes.
- Export crawl rows for spreadsheet or custom analysis.
- Add project-specific extraction or issue rules in a fork.
Practical starting point: Benchmark a representative subdirectory against an established crawler, compare URL discovery and rendered output, measure memory use, and keep a reproducible configuration file.
Limitations, security and operating cost
- Desktop resources constrain very large crawls and JavaScript rendering can increase time and memory use.
- Open source does not guarantee a mature issue model, support response or update cadence.
- Crawler findings still need log, analytics and Search Console evidence for prioritization.
Open source removes one form of lock-in, but it does not remove engineering time, model or API charges, browser/proxy costs, data-provider terms, authentication work, backups or upgrade risk. Map every external service and every write-capable action before production use.
LibreCrawl compared with alternatives
| Option | Choose it when | Trade-off |
|---|---|---|
| Screaming Frog | mature configurable technical crawling | commercial license above the free limit |
| SiteOne Crawler | SEO plus security, accessibility and performance | broader scope, different workflow |
| SEOnaut | self-hosted recurring audits | server and database setup instead of desktop use |
The comparison is task-based, not a claim that one product is universally better. A narrow library may outperform a suite inside its framework, while a mature commercial crawler may be cheaper than maintaining an open tool at large scale.
A seven-step evaluation before adoption
- 1. Define one decision and a bounded test set before installing or connecting accounts.
- 2. Pin the repository revision or release and record the configuration used.
- 3. Verify several outputs against the live page, source console or another independent tool.
- 4. Separate deterministic observations from scores, estimates and model-written recommendations.
- 5. Measure false positives, missing coverage, runtime and provider cost on a realistic sample.
- 6. Use least-privilege credentials; require approval for edits, submissions, purges or publishing.
- 7. Keep raw exports and a rollback plan so the result can be audited after an update.
Our independent take
Its strongest differentiator is inspectability. Adoption should still be decided by crawl parity and false-positive rate on the team's own site. That is also the decision boundary: keep the tool if it produces reproducible evidence and reduces work on a real site; reject it if the team mainly receives more scores, prose or issue volume without clearer decisions.
Frequently asked questions
Is it really open source?
The GitHub API reported MIT on 19 October 2026. Review the repository's license file and dependency licenses for the exact rights and obligations. A connected cloud API or hosted service can have separate terms even when the client code is open.
Does GitHub popularity mean it improves rankings?
No. Stars and forks indicate attention and reuse, not ranking lift, data accuracy or suitability for a particular site. Use a controlled evaluation with Search Console, analytics and manually verified output.
Who is it best for?
LibreCrawl is best suited to independent consultants and technical teams that value local control and are willing to test a younger crawler. It is a poor fit when the team cannot operate its runtime, verify its evidence or own the permissions it requests.
What should be tested first?
Use one representative workflow: Create a local inventory of titles, headings, canonicals and status codes. Record inputs, raw output, time, failures and any external cost, then compare with the team's current method.
Can it replace a commercial SEO suite?
Usually only for a defined slice of work. Open-source workflow and audit tools rarely include the same proprietary backlink index, historical SERP coverage, support organization, permissions and polished client reporting as a mature paid suite.
How to Use LibreCrawl: Quick Start
This workflow is condensed from the project's official README and documentation. Run it first on a test site, test property or local environment; check the linked source again when versions change.
Prerequisites
- Docker and Docker Compose for the recommended path
- Git
- Enough local memory and disk for the crawl and optional JavaScript rendering
Install and run
git clone https://github.com/PhialsBasement/LibreCrawl.git
cd LibreCrawl
cp .env.example .env
docker compose up -d

# Open the local interface
http://localhost:5000
First-use workflow
- Clone the repository and review the sample environment file.
- Keep LOCAL_MODE enabled only for private local use and start the Docker services.
- Open the local UI and create a small crawl with conservative URL and concurrency limits.
- Export the result and compare discovered URLs, canonicals and rendered output with a second crawler.
How to confirm it worked
The local interface opens, the bounded crawl completes and exported rows match manually checked pages without unexplained URL inflation.
Before production use
The automatic startup script can install dependencies and browsers. Review it before use, never expose unauthenticated local mode to the internet, and benchmark resource use before large crawls.
Official Quick Start source: PhialsBasement/LibreCrawl README.
Sources reviewed
Editorial review updated 19 October 2026. Repository statistics, documentation, dependencies and hosted-service terms can change. Verify the linked official sources before installation, procurement or deployment.